ModelXray
- Project
- ML Model Failure Discovery & Regression Platform
- Focus
- ML failure discovery
- Platform
- Python / Next.js
- Status
- Independent project
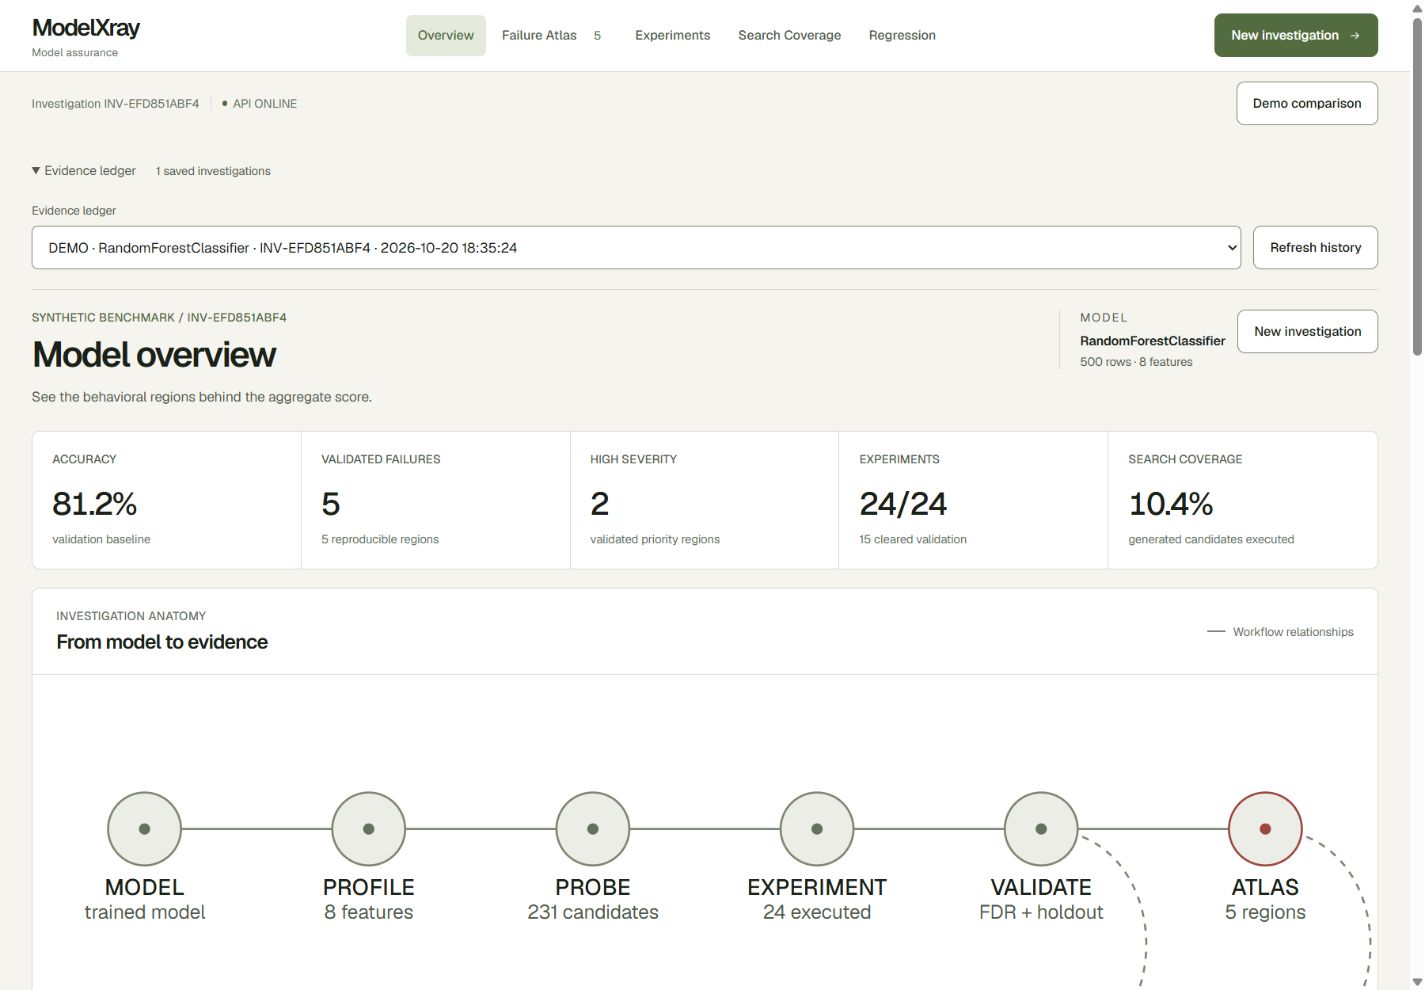
Local synthetic benchmark: 500 evaluation rows, 24 executed experiments and five validated failure regions. Results restored from the evidence ledger.
(Overview)
A black-box ML failure-discovery and regression engine that investigates where a classifier stops being reliable.
An aggregate accuracy score can hide systematic failures in specific data subgroups. Finding those weaknesses requires evidence, a search budget and checks against false discoveries.
- Python
- FastAPI
- Scikit-learn
- SciPy
- Next.js
- TypeScript
(The build)
ML Model Failure Discovery & Regression Platform
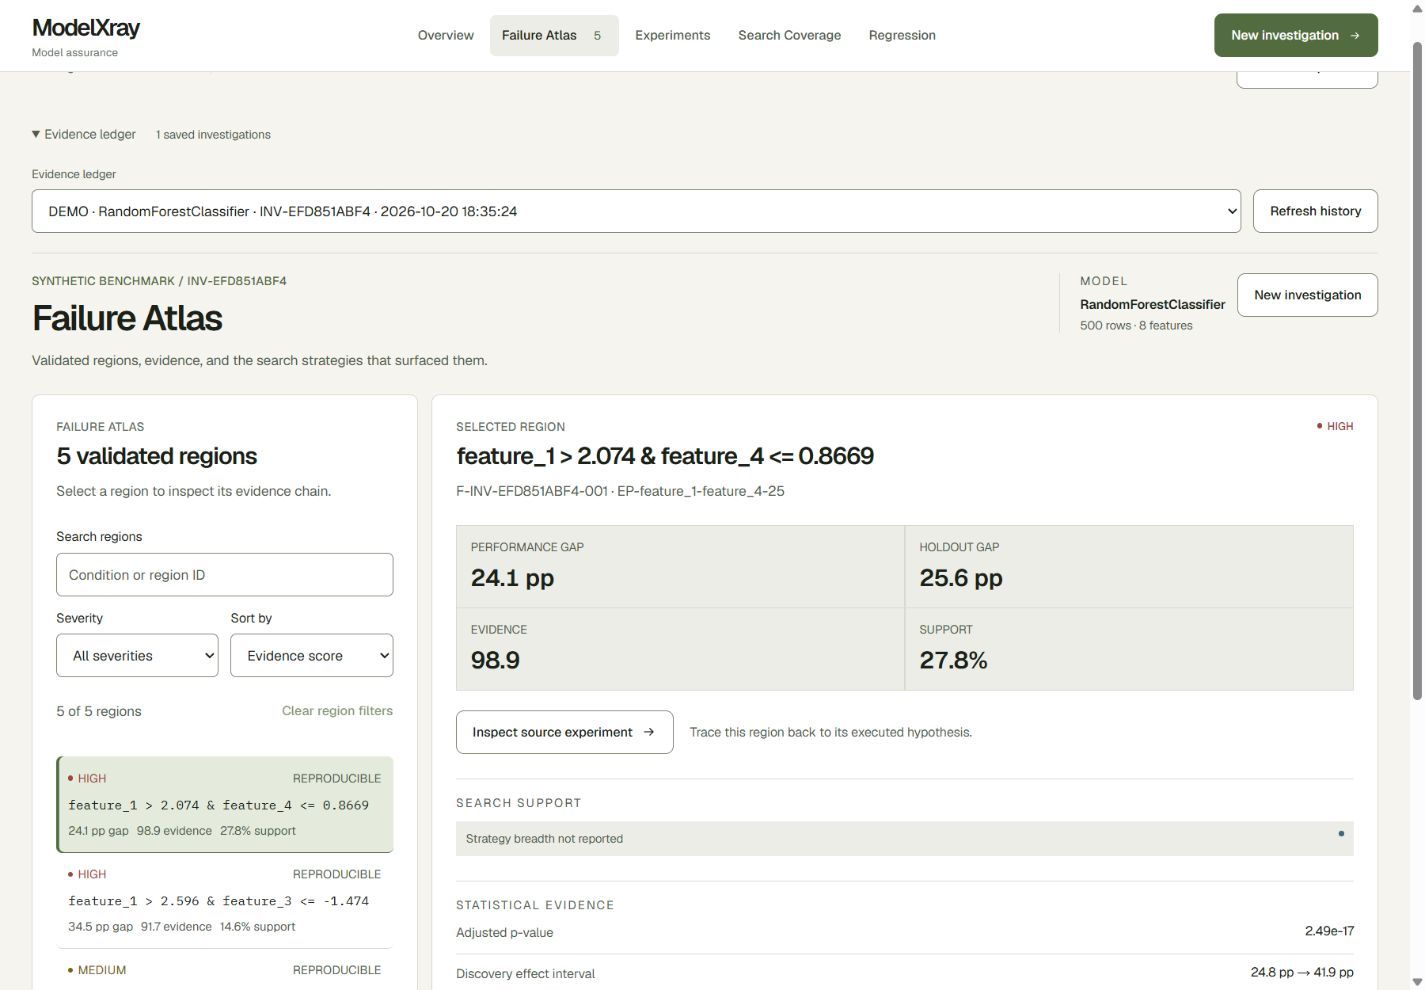
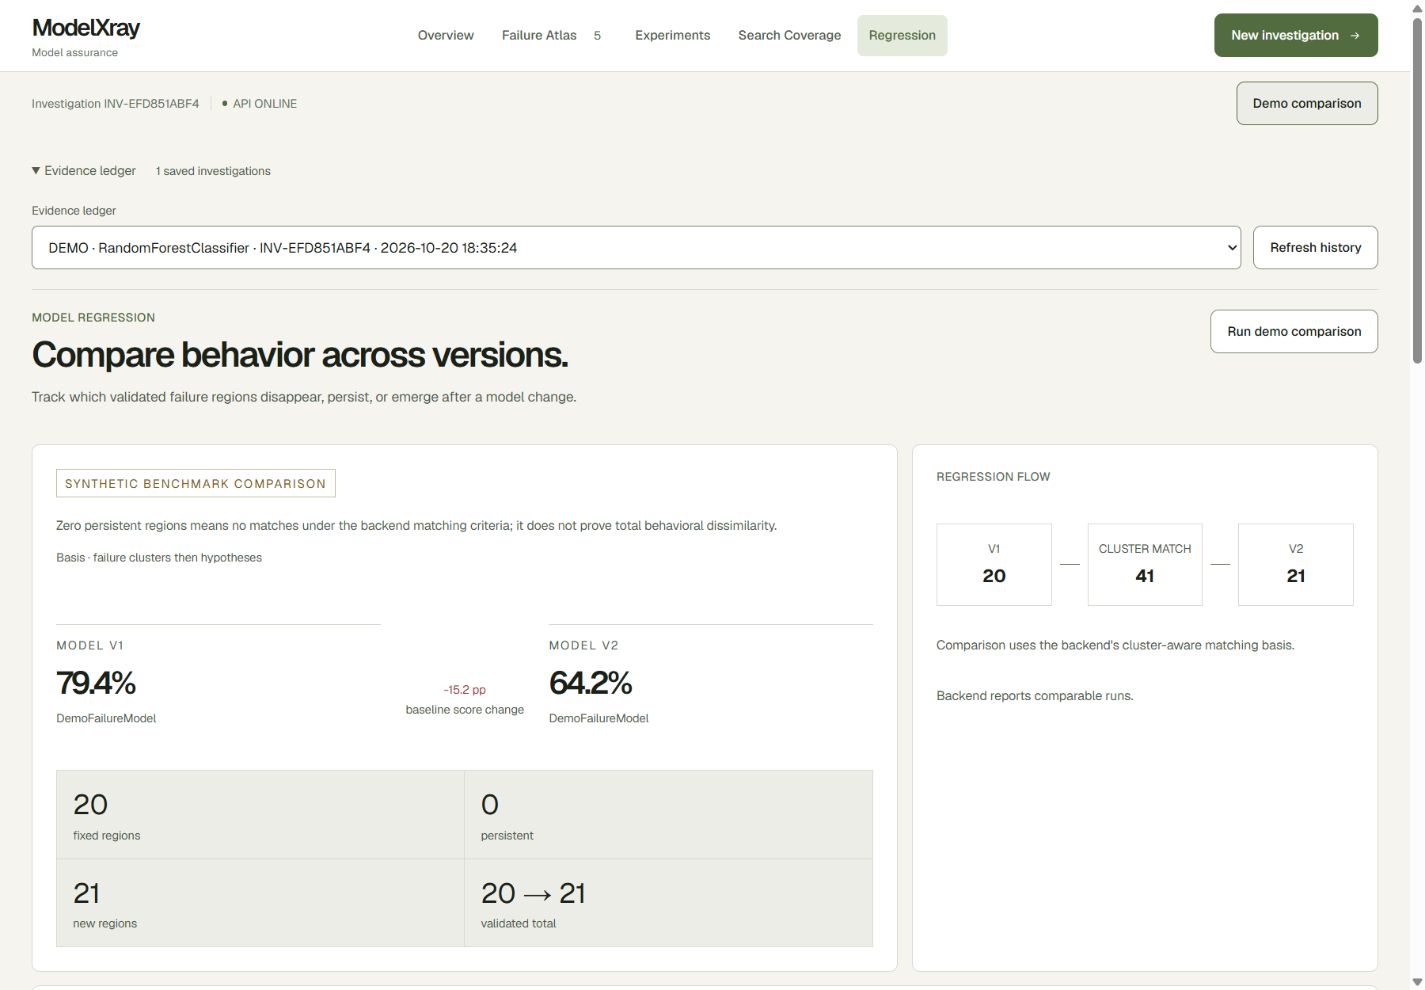
ModelXray profiles an evaluation dataset, generates failure hypotheses, allocates a bounded experiment budget and runs candidates through statistical screening, FDR correction and a disjoint holdout gate. A failure atlas preserves the evidence for comparisons between model versions.
(Engineering details)
04Multiple hypothesis families share one validation pipeline
Benjamini–Hochberg FDR over the executed experiment family
Holdout validation with effect and confidence-interval gates
Cluster-aware model regression and reproducible run certificates
From inputs
to evidence.
The investigation keeps discovery, validation and version comparison in one reproducible flow.
- 01
Model + dataset
- 02
Profile & split
- 03
Candidate families
- 04
Budgeted experiments
- 05
Fisher / BH-FDR
- 06
Holdout gate
- 07
Failure atlas
- 08
Version regression
Historical MXBench / 30 seeds / budget 24
- 0.90
Discovery in specified covariate-shift and correlated-feature scenarios
- 0.00
Fabrication-only FDR on the C0b control
- 1.00
Counterexample replay validity in the reported snapshot
(Evidence & context)
The repository’s historical MXBench snapshot reports 0.90 discovery for covariate-shift and correlated-feature scenarios, 0.00 fabrication-only FDR on C0b, and 1.00 counterexample replay validity (30 seeds, budget 24). These are scenario-specific results, not general reliability guarantees.
The current development engine includes later search strategies. The repository explicitly requires a fresh full multi-scenario benchmark before a new release claim. Boundary-sensitivity evidence is approximate and does not establish causality.
Read the repository ↗